Cache Doesn't Make Your System Faster. It Just Moves the Complexity Somewhere Else.
There's a dangerous misconception in software engineering: that adding a cache is a performance solution. It isn't. It's a trade-off – one that swaps database load for a new set of problems around consistency, failure modes, and operational complexity.
Every caching decision ultimately comes down to one question: who is responsible for writing to the cache, and when does that write happen?
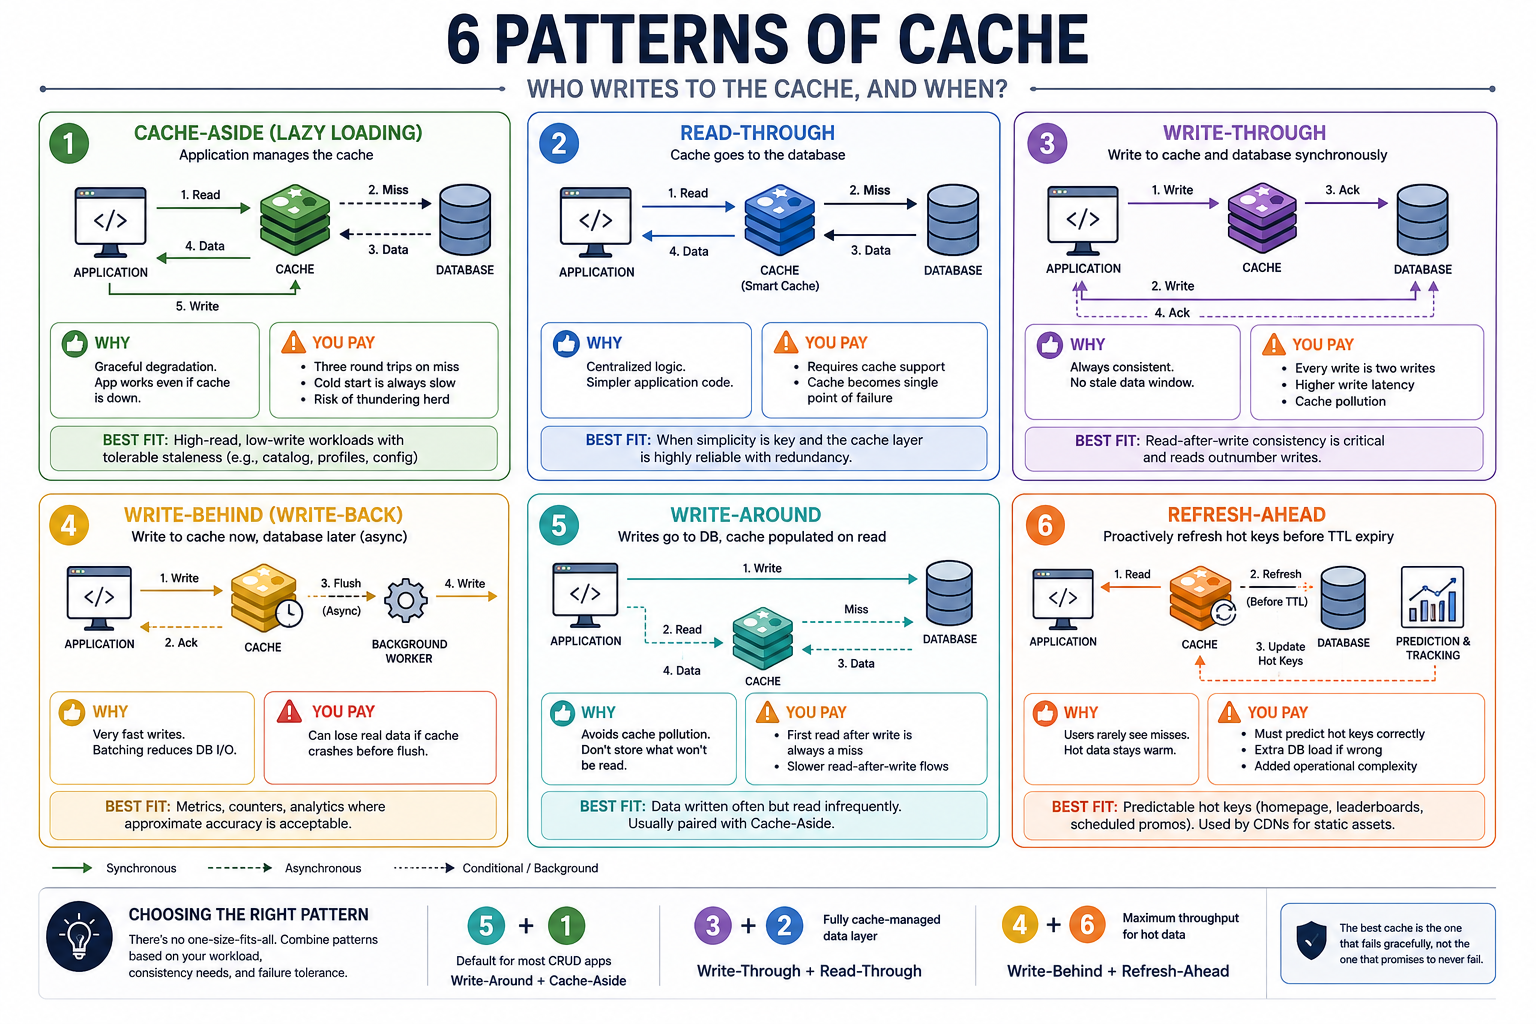
Answer that question differently and you get six distinct patterns. Each one makes sense in a specific context and falls apart in others. Here's a map of all six – not just what they are, but why you'd reach for each one.
1. Cache-Aside (Lazy Loading)
The pattern: The application manages the cache itself. On every read, it checks the cache first. If the data is there (a hit), return it immediately. If not (a miss), go to the database, fetch the data, write it into the cache for next time, and return it to the caller.
Why it's the most popular pattern: The application never has to trust the cache to be available. If Redis goes down, your app keeps working – it just queries the database directly on every request, which is slower but not broken. This graceful degradation is a huge operational advantage.
What you're paying for:
- Every cache miss costs three round trips: check cache → query DB → write to cache. That's three network hops instead of one.
- The first request for any piece of data is always slow – the cold start problem. After a deployment or a cache flush, users feel this.
- If two requests miss at the same moment, you can end up with a thundering herd – both threads query the database and both write to cache, duplicating work.
Best fit: High-read, low-write workloads where you can tolerate data being slightly stale within your TTL window. Product catalog pages, user profile lookups, configuration data.
2. Read-Through
The pattern: Superficially similar to Cache-Aside, but the key difference is who goes to the database. In Read-Through, the application talks only to the cache. When a miss occurs, the cache itself fetches the data from the database, stores it, and returns it. The app never touches the DB directly.
Why it's useful: The cache-population logic lives in one place – inside the cache provider configuration – rather than scattered across every service or function that reads data. Your application code becomes simpler: ask cache, get answer. No conditional logic, no fallback handling.
What you're paying for:
- You need a cache provider that actually supports this pattern (some do natively, others require plugins or proxies). You can't implement this with plain Redis and application code alone.
- More critically: the cache becomes a single point of failure. If it goes down, your entire read path goes with it, because the application no longer has the logic to reach the database directly. You've traded simplicity for fragility.
Best fit: Applications where code simplicity is paramount and the caching layer is highly reliable with its own redundancy and failover. Common in managed cache services where the provider handles the DB integration.
3. Write-Through
The pattern: Every write operation updates both the cache and the database synchronously – the application waits for both writes to complete before returning a success response to the client.
Why it's appealing: The cache is always perfectly consistent with the database. There's no stale data window, no need for a separate invalidation mechanism, no reconciliation logic. What's in cache is exactly what's in DB, always.
What you're paying for:
- Every single write is now two writes: one to cache, one to DB. Your write latency doubles (at minimum). For write-heavy workloads, this can be catastrophic.
- You end up with cache pollution: you're storing data for every write, but not every write is something that will ever be read from cache. If a user updates their shipping address once and never visits that page again, you've consumed cache memory for data that will never serve a hit.
Best fit: Systems where read-after-write consistency is critical and reads outnumber writes. Banking dashboards, inventory systems where you can't afford to show stale numbers.
4. Write-Behind (Write-Back)
The pattern: The application writes to the cache only and immediately returns success to the client. A background worker (or the cache itself) flushes the data to the database asynchronously – often batching multiple writes together before persisting them.
Why it's fast: From the client's perspective, a write completes in microseconds – the cache write is as fast as cache gets. By batching many small writes into larger DB operations, you also reduce database I/O significantly. If 1,000 users increment a view counter in ten seconds, that can become one DB write instead of 1,000.
What you're paying for: This is the only pattern in this list that can lose real data. If the cache crashes before the background worker flushes pending writes to the database, those writes are gone permanently. There's no recovery path.
This isn't a hypothetical edge case – cache nodes restart, pods get evicted, machines fail. Data loss is a real operational risk.
Best fit: Metrics, counters, view counts, analytics – data where approximate accuracy is acceptable and the cost of occasional loss is low. Never use this for financial balances, order records, user-generated content, or anything where data loss has real consequences.
5. Write-Around
The pattern: Writes go directly to the database, bypassing the cache entirely. The cache only gets populated when someone actually reads the data (typically via Cache-Aside).
Why it makes sense: Not all data that gets written will ever be read back through the cache. Audit logs, archival records, bulk-imported data – these might be written once and queried rarely if ever. Write-Through or Write-Behind would waste cache memory storing this data speculatively. Write-Around avoids that entirely.
What you're paying for:
- The first read after any write will always be a cache miss. The data is in the DB but not in cache, so that first request pays the full database round trip.
- If read-after-write is a common user flow in your application ("user submits form, immediately sees their submission"), the experience will feel slower than expected.
Best fit: Data that's written frequently but read infrequently or unpredictably. Write-Around is almost always paired with Cache-Aside as a combo: writes go around the cache, reads populate it lazily. This is arguably the most common real-world implementation.
6. Refresh-Ahead
The pattern: A background worker proactively refreshes hot keys in the cache before their TTL expires, based on prediction of which keys are about to be needed. The goal is that by the time a user requests the data, it's already fresh in cache – they never experience a miss.
Why it's powerful: In theory, your users never wait. High-traffic keys – the homepage hero banner, the top 10 trending items, a frequently-viewed product – stay perpetually warm. There's no cold start and no thundering herd, because the cache is always pre-populated.
What you're paying for:
- The system has to correctly predict which keys will be hot. If the prediction model is wrong – if it refreshes keys that stop being popular, or misses ones that suddenly spike – you're generating unnecessary database load for nothing.
- This pattern adds significant operational complexity: you need a separate process to manage predictions, track access patterns, and orchestrate refreshes.
Best fit: Only worth the complexity when you have a well-defined set of hot keys that are genuinely predictable – homepage content, leaderboard data, scheduled promotional items. This is the pattern used by CDNs for static assets, where the "prediction" is simply: refresh before CDN edge expiry.
Choosing the Right Pattern
The patterns aren't mutually exclusive. Production systems routinely combine them:
- Write-Around + Cache-Aside is the default combo for most CRUD applications.
- Write-Through + Read-Through gives you a fully cache-managed data layer, at the cost of a critical dependency on cache availability.
- Write-Behind + Refresh-Ahead can squeeze extraordinary throughput out of a hot dataset, but requires significant investment in resilience and monitoring.
The question to ask isn't "how do I make this faster?" It's "where am I willing to move the complexity?" Cache shifts load from the database to the cache layer – but it introduces staleness risk, failure modes, and operational overhead that didn't exist before.
Pick the pattern that puts that complexity somewhere your team is prepared to handle it.
The best cache is the one that fails gracefully, not the one that promises to never fail.