Understanding the backbone of every data-driven organization, a “starter kit” for anyone entering the world of Data Engineering
Modern organizations breathe data. Behind every dashboard, every metric, every “data-driven decision”, there’s a hidden machinery ensuring the right data flows in the right format to the right place. That machinery is ETL (Extract – Transform – Load), one of the foundational pillars of data engineering.
Today I will expand those definitions into a cohesive, narrative-style guide to help you grasp ETL intuitively, and more understand how these concepts show up in real-world systems.
1. Why ETL Exists (and Why It Still Matters Today)
At its core, ETL solves one universal problem:
Data rarely comes clean, complete, or consistent.
Systems speak different “languages”: your CRM stores customers one way, your ERP stores sales another way, and your web analytics tool tracks behavior with yet another structure. ETL is the translator, optimizer, and transport system all in one.
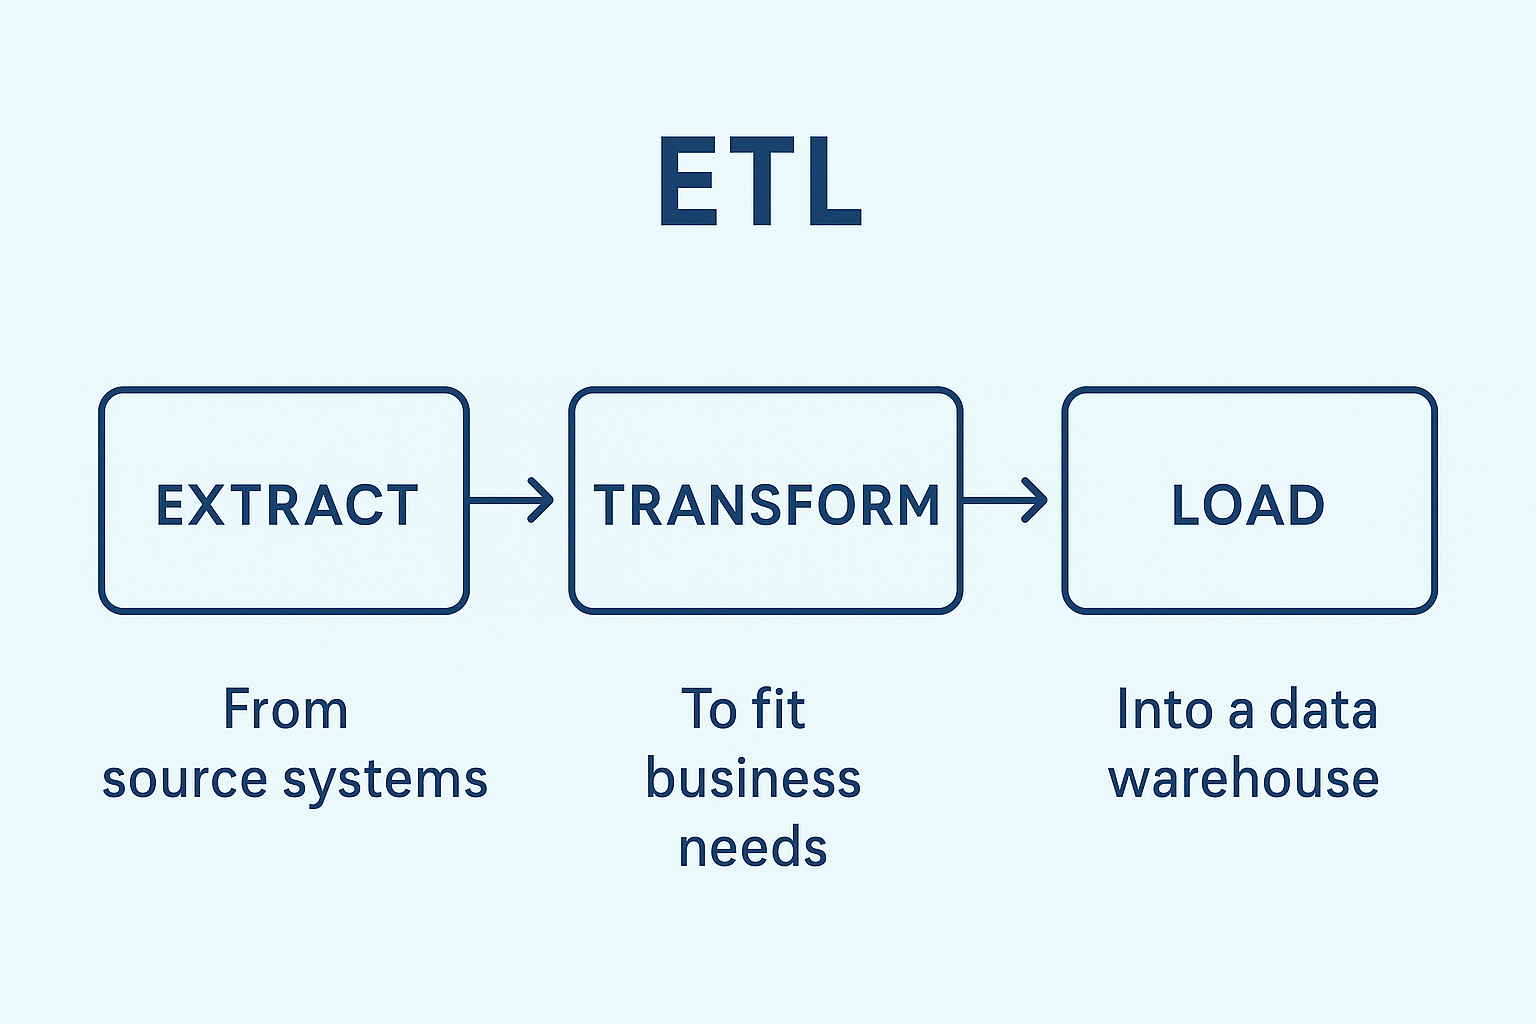
In the uploaded material, ETL is defined as the process that:
- Extracts data from source systems
- Transforms it to meet business needs
- Loads it into a data warehouse
This simple-sounding pipeline is surprisingly deep. Let’s break it down the way a modern data engineer thinks.
2. Extract: Getting the Data Out
Extraction involves retrieving data from multiple source systems: CRM, ERP, APIs, logs, etc.
The file defines Extract as the process of retrieving data from different systems.
2.1 Data Discovery & Data Profiling
Before extraction, engineers must understand the data’s structure and quality.
-
Data Discovery: Identifying which systems hold the needed data
-
Data Profiling: Understanding completeness, outliers, and inconsistencies
Many ETL failures come not from code bugs, but from “unknown unknowns” hidden inside inconsistent source data.
2.2 Staging Area – The Temporary Parking Lot
Extracted data is usually placed in a staging area, where nothing is cleaned yet, it’s raw, messy, and untouched.
This is where engineers can safely inspect, experiment, and diagnose issues before moving forward.
3. Transform: Cleaning, Shaping & Making Data Useful
Transformation is the heart of ETL. There are many transformation concepts:
3.1 Cleaning & Standardization
-
Data Cleaning: Fixing errors like misspellings, nulls, invalid formats
-
Data Validation: Ensuring values follow the rules (e.g., valid email format)
-
Data Conforming: Aligning labels between incompatible systems
3.2 Business Logic Transformation
These rules shape the data into something analytically valuable:
-
Business Rules: Logic like tax calculation, discount rules, SCD behaviors
-
Data Aggregation: Summaries like monthly totals
-
Granularity Decisions: Transaction-level or daily-level data?
3.3 Schema & Modeling Concepts
The glossary also covers key modeling structures:
-
Star Schema
-
Snowflake Schema
-
Dimension Tables & Fact Tables
-
Slowly Changing Dimensions (SCD)
These patterns dictate how well your data warehouse supports business queries.
3.4 Security-related Transformations
Modern ETL must protect sensitive data:
-
Anonymization
-
Masking
-
Encryption
Many startups today must pass SOC 2 / GDPR audits, secure ETL pipelines are a competitive advantage.
4. Load: Delivering Data to Where It Matters
Loading moves transformed data into the target system, usually a data warehouse.
4.1 Full Load vs Incremental Load
Two major strategies:
-
Full Load: Reload everything
-
Incremental Load: Only load what changed
Incremental loading is essential for scalable pipelines.
4.2 Fact Table Loading
A specialized process involving metrics, derived values, and relationships.
4.3 Data Archiving & Purging
The material also highlights the lifecycle of data:
-
Archiving: Move old data to long-term storage
-
Purging: Delete data no longer needed
Archiving isn’t just about storage, it impacts query performance, cost, and compliance.
5. Beyond ETL: The Supporting Ecosystem
What makes ETL production-ready isn’t just the pipeline, it’s the ecosystem around it.
5.1 Orchestration & Automation
-
ETL Process Automation
-
ETL Scheduler
-
ETL Orchestration (e.g., Airflow)
These tools ensure that pipelines run on time, fail gracefully, and notify humans when needed.
5.2 Monitoring, Logging, and Auditing
Mission-critical for production systems:
-
ETL Monitoring
-
ETL Logging
-
ETL Audit Trail
Without these, debugging becomes a nightmare.
5.3 Governance & Stewardship
The PDF closes with organizational-level concerns:
-
Data Governance
-
Data Stewardship
These ensure data remains accurate, accessible, and compliant over time.
6. Modern Variants: ELT, Data Lakes, and Lakehouses
Some key modern patterns:
- Data Lake & Data Lakehouse
Many companies today adopt ELT instead of ETL-extracting and loading raw data first, then transforming it using the power of cloud warehouses like BigQuery or Snowflake.
But regardless of architecture, the foundational concepts from ETL terminology still apply.
7. Final Thoughts: Why Every Data Engineer Should Master ETL
ETL is not “old tech.” It’s the backbone behind:
- Analytics
- Machine learning
- Business dashboards
- Customer personalization
- Fraud detection
- Automation and reporting systems
You can’t build good ML models with bad data.
You can’t analyze customer behavior if sources don’t align.
You can’t scale data science if your pipelines break at 2 a.m.
ETL is the invisible engine that makes data usable.
And mastering the terminology is the first step toward designing pipelines that are fast, clean, secure, and resilient.