If you’ve built anything with LLMs in the last couple of years, you’ve built a RAG pipeline. Embed the query, search a vector store, stuff the top chunks into a prompt, let the model talk. It’s the “Hello World” of grounding LLMs in real data – and for a long time, it was enough.
It isn’t anymore.
The moment your use case involves multi-hop reasoning, tool calls, or relationships between entities scattered across thousands of documents, naive RAG starts cracking. That’s given rise to two evolutions worth understanding deeply: Agentic RAG and Graph RAG. They solve different problems, and confusing them will cost you weeks of rebuilding. Let’s walk through all three, step by step.
1. Classic RAG: Fast, Simple, and Blind to Nuance
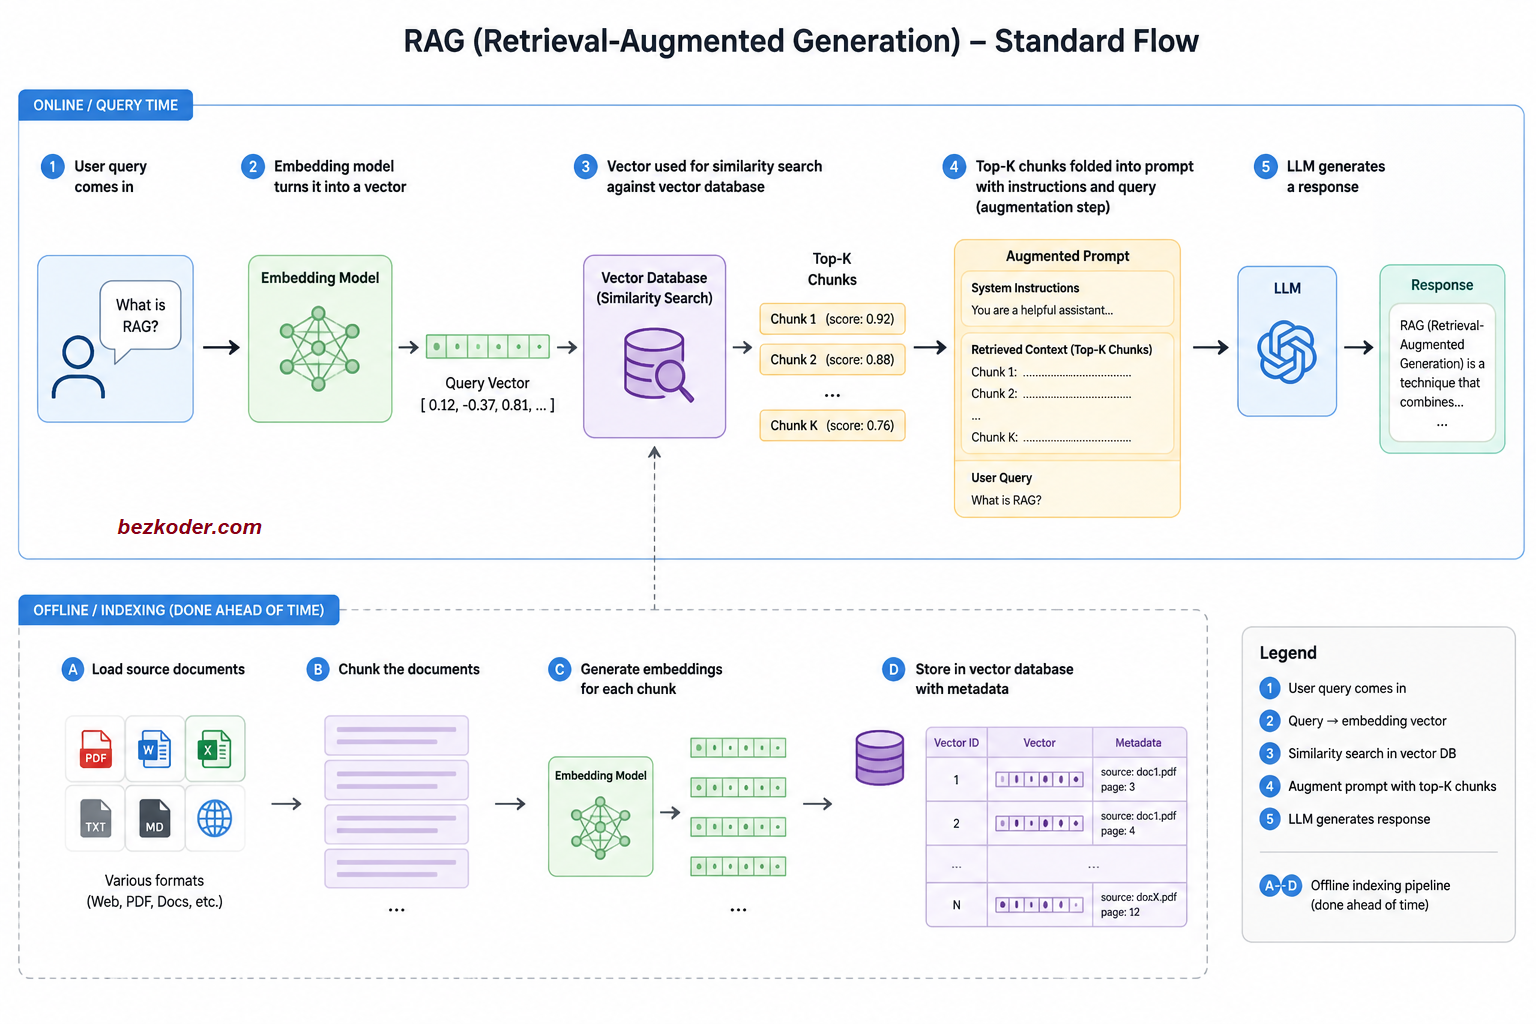
The original recipe is almost suspiciously simple:
- User query comes in.
- An embedding model turns it into a vector.
- That vector is used for a similarity search against a vector database that was populated ahead of time through offline indexing (your documents, chunked and embedded, sitting in an index with metadata).
- The system pulls back the top-K chunks – the pieces of text that are mathematically “closest” to the question.
- Those chunks get folded into a prompt alongside the system instructions and the original query – this is the augmentation step.
- The LLM generates a response from that augmented prompt.
That’s it. One pass, no branching, no second-guessing. It’s a straight line from question to answer.
The appeal is obvious: it’s cheap, it’s fast, and it’s predictable. The catch is also obvious once you’ve used it long enough – it has no idea whether the chunks it retrieved are actually good. If the top-K results are irrelevant, outdated, or simply insufficient to answer the question, the pipeline has no mechanism to notice or correct course. It retrieves once and commits, for better or worse.
This works beautifully for narrow, well-scoped knowledge bases – internal FAQs, product docs, single-source Q&A. It starts falling apart the moment a question needs judgment about what to retrieve, or needs more than one source to answer properly.
2. Agentic RAG: Giving the Pipeline a Brain (and a Loop)
Agentic RAG doesn’t replace the retrieval step – it wraps it in decision-making. Instead of a straight line, you get a loop with actual agents making choices along the way.
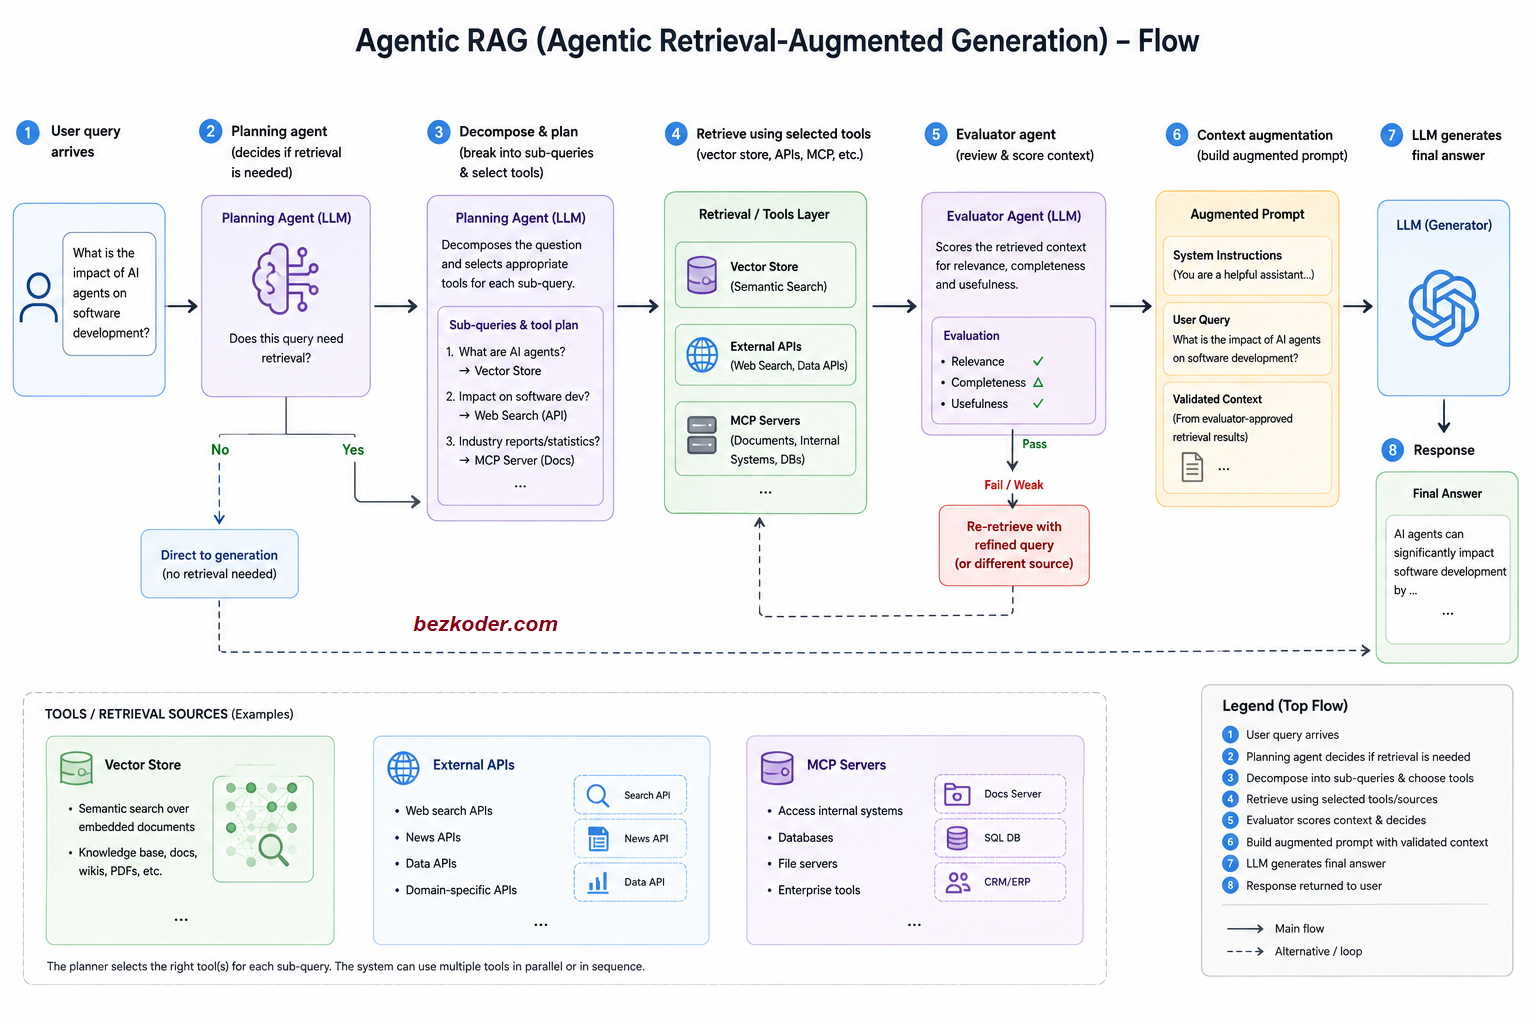
- User query arrives, same as before.
- But now it hits a planning agent – an LLM with its own system prompt whose entire job is to ask: does this even need retrieval?
- If no, the query goes straight to generation as a direct query.
- If yes, the planning agent breaks the question into sub-queries and decides which tools are appropriate for each one.
- The retrieval step itself is no longer just a vector database. It might hit a vector store, call external APIs, or reach out through MCP servers – whatever tool the planner selected.
- Here’s the key addition: an evaluator agent reviews what came back. It actively scores the retrieved context and decides – pass, or re-retrieve?
- If the context is weak or incomplete, it loops back to retrieval with a refined query, possibly hitting a different source entirely.
- Once the context passes the evaluator’s bar, it moves to context augmentation – system prompt, user query, and the validated retrieved context, combined.
- The LLM writes the final answer from either the direct query or the augmented prompt.
- Response.
What you’re really looking at is RAG with self-correction. The system can recognize when it’s retrieved garbage and go fetch something better, instead of confidently hallucinating an answer from weak context. It can also decide retrieval isn’t needed at all – not every question requires a database lookup, and treating every query identically wastes both latency and money.
The tradeoff is real, though: every loop is another LLM call. Agentic RAG is slower and pricier per query than classic RAG. You’re trading latency and cost for reliability and reasoning depth. That trade makes sense for customer support escalations or research assistants – it makes much less sense for a simple “what are your store hours” bot.
3. Graph RAG: When the Relationships Are the Answer
This is the one that looks the most intimidating on a whiteboard, and for good reason – it’s solving a fundamentally different problem.
Vector similarity search is great at finding semantically similar text. It is genuinely bad at answering questions like “how does Entity A relate to Entity B across these twelve documents?” – because that’s not a similarity problem, it’s a connectivity problem. Graph RAG exists to handle exactly that.

The flow:
- User query comes in.
- Immediately, query classification decides the strategy: is this a specific, narrow question (→ local search) or a broad, thematic one (→ global search)? This branch point matters – it determines almost everything downstream.
On the local search path:
- Context augmentation assembles entities, relationships, and text chunks relevant to the query.
- An LLM generates a response directly from that assembled, linked context.
- In parallel, an embedding model converts the query for similarity search.
- A vector database (again, built via offline indexing) finds matching entities – returning the top-K entity IDs, not just text chunks.
- Those entity IDs feed into a knowledge graph, also built offline, which traverses linked context across connected nodes – pulling in everything relationally tied to those entities.
- That linked context flows back into context augmentation, closing the loop, and the LLM produces the final response.
On the global search path, the system reasons over the entire corpus rather than a local neighborhood:
- Community reports – pre-generated summaries of clusters of related entities, built during offline indexing – are loaded in batches.
- An LLM mapping call processes each batch: extract and rate key points relevant to the query, using a system prompt built for exactly that.
- The output – key points plus ratings – flows into a filter that keeps only the top-ranked points and discards low-rated noise.
- This repeats batch after batch until the entire dataset has been processed.
- Finally, an LLM final synthesis call takes the accumulated top-ranked points, combines them with the system prompt and user query, and writes the actual answer.
This is a genuinely heavier architecture – there’s a knowledge graph to build and maintain, community reports to pre-generate, and a multi-batch mapping process for global queries. But it’s solving for something neither plain RAG nor Agentic RAG can: questions that require understanding structure, not just finding similar text. “What are the major themes across this entire dataset?” or “How is this regulation connected to that subsidiary’s filings?” are graph questions wearing a RAG costume.
So, Which One Do You Actually Need?
| RAG | Agentic RAG | Graph RAG | |
|---|---|---|---|
| Core mechanism | Single-pass vector similarity | Planning + evaluation loop over multiple tools | Entity/relationship traversal + community summarization |
| Best for | Narrow, well-scoped knowledge bases | Multi-source, multi-step questions needing judgment | Questions about relationships, themes, or structure across a large corpus |
| Latency / cost | Low | Medium–high (multiple LLM calls per query) | Medium (local) to high (global, batch-based) |
| Self-correction | None | Yes – evaluator agent can trigger re-retrieval | Implicit – graph traversal pulls in connected context automatically |
| Indexing complexity | Vector store only | Vector store + tool/API integrations | Vector store + knowledge graph + community reports |
| Weak spot | Can’t judge its own retrieval quality | More moving parts, more cost, more latency | Heaviest to build and maintain |
None of these architectures is strictly “better”. They answer different questions well. If your data lives in tidy, narrow silos and your users ask direct questions, plain RAG is still the right call – don’t reach for a knowledge graph to answer “what’s our refund policy”.
If your system needs to decide how to find an answer, possibly across tools and APIs, and verify it found a good one, Agentic RAG earns its extra latency.
And if the actual value lives in the connections between things – across thousands of documents, with thematic or relational questions that vector similarity simply can’t resolve – Graph RAG is doing work nothing else in this lineup can do.
The mistake isn’t picking the “wrong” one. It’s picking based on hype instead of the actual shape of your data and your questions.